Hi qiime2 community.
(This post is long, but needs some context.) The short story is that I think that the qiime2 classification (or taxa collapse) step are stopping species-level classification for vaginal swab microbiome sequenced using 16S.
Is there a way to ‘force’ the species level attribution? My thinking is that when blasting the representative sequences on NCBI, we can get a species level attribution.
I am working on 16S sequencing of vaginal swabs. I am using the full V3-V4 and the merged forward-reverse reads for rep-seqs average length 350pb. And I used my normal qiime2 pipeline and had decent results. And I made a lot of analysis using genus-level attributions. Common thinking is 16S doesn’t provide Specie-Level attributions. But in the context of vaginal swabs, it is more interesting to have species level attributions, especially for the lactobacillus species.
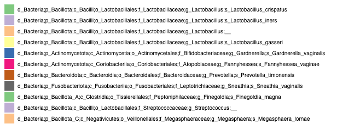
I get Lacto crispatus, iners and gasseri. But Jensenii and delbrueckii get mixed up as one. And gets no species level name.
At work, we found a project addressing this problem, named vSpeciateDB. Which I was able to run on the same 16S dataset and got all species level attributions for Lacto species. But running the code is not simple, with a lot of shell function calls and python calls.
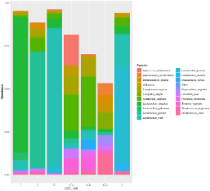
And then, I was stuck making the downstream analyses in R. And I much prefer the qiime2 graph environment, with the qzv and sample-classifier(for machine learning), etc. (R phyloseq barplots have weird taxa order, hard to read color scheme, etc.)
But I still think that my V3-V4 16S sequencing has enough information to provide me with species level attributions. It is a matter of making it work with qiime2.
The profiler output for vSpeciateDB outputs only the species level labels (not the full kpcofgs). And when imported into qiime, I get a big ‘unassigned’ attribution for lacto crispatus.
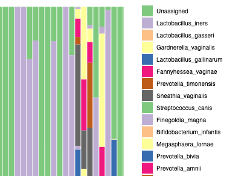
I used vSpeciateDB output linking ASV -> Species on the rep-seqs.qza and the ASV table.qza (from qiime2). I used a .tsv that I imported as a qiime2 taxonomy.qza artefact, but it didn’t work properly.
Now, this is not looking like a great solution. I prefer to have qiime2 style reproducible code. Here, for vSpeciateDB inside qiime2, for each future project, I would have to make the taxonomy, fuzzy-match the species names to get the full GSR style taxonomic labels, re-package .tsv into qiime, and etc.
So, I wanted to train a reference database in qiime2. To be able to make the taxonomy.qza file for all my future projects.
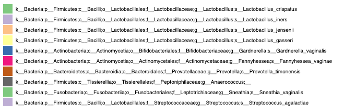
And I managed to get it working with the sequences from vSpeciateDB. But the DB that I imported contained ~1,1k sequences. Which seems very low compared to the usual 80k-100K for other databases. And I found the full extent of the 5k sequences form vSpeciateDB, but it stopped working properly, with the ambiguous attributions in qiime2.
So, my next attempt was to ‘clean’ the lactobacillus species from the GSR database (a merge of GreenGenes, Silva and RDP) so that the ambiguous sequences would resolve to 1 species only. I took the sequences from the DB as a text file and removed all the lacto species. Then I used an online tree builder (clustal omega) and using the full length 16S sequences from the lacto species, selected clusters to manually re-import into the GSR DB. And make a qiime2 artefact.
And it worked! I got all my lacto to species level attributions, No unassigned. No g__lacto;s__ . So, for good measure, I re-did the manual steps as code! Using R to manipulate the files, run the sequence alignments using clustal, re-merge the DB sequences and make clean sequences for taxonomy training. The code works great! But I could not get the classifiers to work properly again! I even have a ‘bootstrap’ series of files, where I allowed some randomness in the clustering and re-ran 10 times. And still, when taxonomy.qza is used, I have at least 1 unknown lacto species (and often a merge of 2 genus too).
My strategy was to subset the Lacto species, compare them in a phylogenetic tree. And select the species that cluster together, to minimize ambiguity for my qiime reference. This image Is a cleaned version. There are still a couple johnsonii interleaved with the gasseri (but it is not my main concern for human samples.)

But over the 20+ attempts to make the reference DB to train my qiime2 classifier, I couldn’t get all the species to resolve properly.
So now, I think that the ambiguous taxonomic attributions are stemming from a qiime2 step, either at the reference 16S DB -> taxonomy.qza step. Or (possibly an easier fix) at the “qiime taxa collapse” step. Is there a way to ‘force’ the qiime module to pick a species instead of giving an ambiguous taxonomic attribution?
I can provide more details! Thanks
All the best, -JA
qiime info
System versions
Python version: 3.8.13
QIIME 2 release: 2022.8
QIIME 2 version: 2022.8.3
q2cli version: 2022.8.0
