# Reformat OTU table for use in FUNGuild
**URL:** https://forum.qiime2.org/t/reformat-otu-table-for-use-in-funguild/33861
**Category:** Other Bioinformatics Tools
**Tags:** taxonomy, otus
**Created:** [December 12, 2025, 5:44am UTC](https://forum.qiime2.org/t/reformat-otu-table-for-use-in-funguild/33861 "2025-12-12T05:44:28Z")
**Posts on this page:** 3
**Page:** 1
### Author:  [@mhog](https://forum.qiime2.org/u/mhog)
#### Post date: [December 12, 2025, 5:44am UTC](https://forum.qiime2.org/t/reformat-otu-table-for-use-in-funguild/33861/1 "2025-12-12T05:44:28Z")
Hey guys,
I hope I’ve put this in the right category! I’m trying to assign my fungal ITS taxa functional guilds with FUNGuild, but to do so I need an OTU able formatted a specific way. I’ve managed to use ITSxpress to extract the ITS1 region, called sequence variants with DADA2, visualised my results, and then clustered my ASVs to 99% OTUs. I assigned taxonomy to the OTUs using a pre-trained Naive Bayes classifier trained on the UNITE database (v.10) with a 99% similarity threshold, which I could then visualise with barplots. I merged the OTU table with the taxonomy by exporting both, converting the .biom files to .tsv files, and then adding the taxonomy column to the OTU table using nano. The resulting .tsv file looks like this:
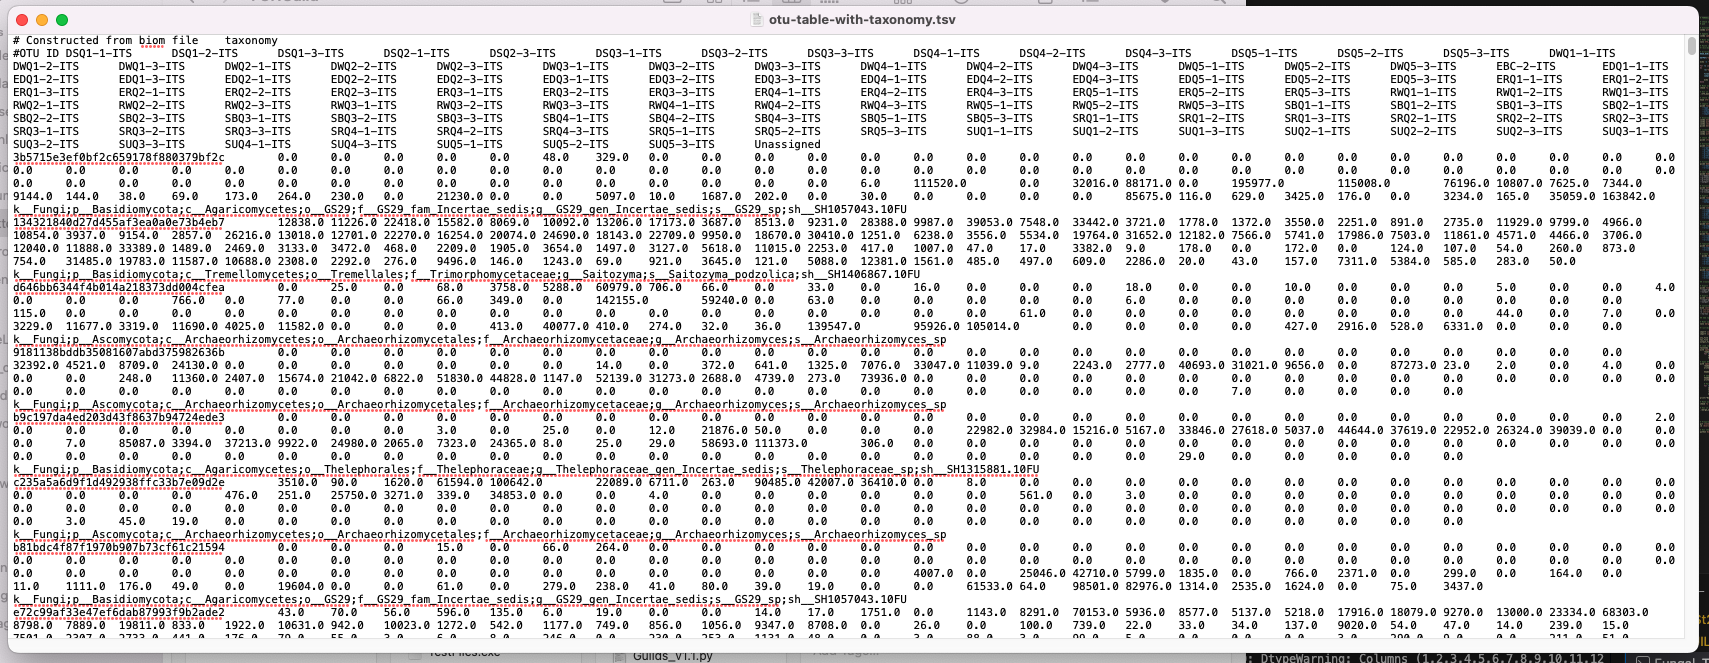
However, the example OTU table given to demonstrate the format required for FUNGuild looks like this:
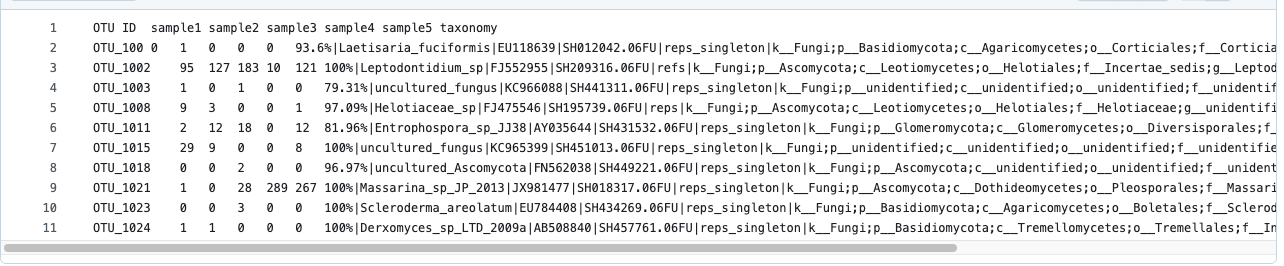
I was wondering if there was a way to change the OTU IDs so that they’re numbered more simply (unlike the long reads in mine), a way to get rid of the first line (“# Constructed from biom file”), and a way to get rid of the # in front of the “#OTU ID” column name. Mine also appears to be a bit more chaotic but I think this is just because of the length of the OTU ID sequences?
Anyway, I think these barriers are stopping FUNGuild from running properly – I don’t think it can recognise the columns unless the formatting is exactly the same. I also thought that it might work better if I could run FUNGuild on genus-level assignments rather than species-level, but I’m not sure if there’s a way to drop species-level assignments easily in this table, so it just shows genus-level assignments and above?
I’ve been following the moving pictures tutorial [here](https://docs.qiime2.org/2024.10/tutorials/moving-pictures/), this thread [here](https://forum.qiime2.org/t/q2-itsxpress-a-tutorial-on-a-qiime-2-plugin-to-trim-its-sequences/5780) for the ITSxpress parts, and this [here](https://github.com/colinbrislawn/unite-train/releases/tag/v10.0-2025-02-19-qiime2-2024.10) for the pre-trained classifier. This is the FUNGuild github page for reference [here](https://github.com/UMNFuN/FUNGuild) too.
This is my code:
```css
# Import raw reads & turn into artifact
qiime tools import \\
--type 'SampleData\[PairedEndSequencesWithQuality\]' \\
--input-path ITS-manifest.tsv \\
--output-path its-demux.qza \\
--input-format PairedEndFastqManifestPhred33V2
# Download ITSxpress as QIIME2 plugin
conda env create -n qiime2-amplicon-2025.10 --file https://data.qiime2.org/distro/amplicon/qiime2-amplicon-2025.10-py310-osx-conda.yml
conda activate qiime2-amplicon-2025.10
conda install -c bioconda -c conda-forge ITSxpress
qiime dev refresh-cache
# Installing ITSxpress for standalone use
conda create -n itsxpressenv -c bioconda -c conda-forge itsxpress
conda activate itsxpressenv
# Check to see ITSxpress plugin is installed
qiime itsxpress
# Extract ITS1 region with ITSxpress
qiime itsxpress trim-pair-output-unmerged \\
--i-per-sample-sequences its-demux.qza \\
--p-region ITS1 \\
--p-taxa F \\
--p-cluster-id 1.0 \\
--p-threads 8 \\
--o-trimmed its1-trimmed.qza
# Visualise quality of trimmed ITS1 reads
qiime demux summarize \\
--i-data its1-trimmed.qza \\
--o-visualization its1-trimmed.qzv
# Call sequence variants with DADA2
qiime dada2 denoise-paired \\
--i-demultiplexed-seqs its1-trimmed.qza \\
--p-trunc-len-r 0 \\
--p-trunc-len-f 0 \\
--output-dir dada2out
# Visualise results
qiime metadata tabulate \\
--m-input-file denoising_stats.qza \\
--o-visualization denoising_stats.qzv
# Export DADA2 table
qiime tools export \\
--input-path its-dada2-table.qza \\
--output-path exported-table
# Cluster to 99% OTUs
qiime vsearch cluster-features-de-novo \\
--i-sequences its-dada2-repseqs.qza \\
--i-table its-dada2-table.qza \\
--p-perc-identity 0.99 \\
--o-clustered-table its-otu-table.qza \\
--o-clustered-sequences its-otu-repseqs.qza
# Tabulate
qiime metadata tabulate \\
--m-input-file its-otu-table.qza \\
--o-visualization its-otu-table.qzv
# Assign taxonomy to OTUs using UNITE pre-trained classifier
qiime feature-classifier classify-sklearn \\
--i-classifier unite_ver10_99_s_19.02.2025-Q2-2024.10.qza \\
--i-reads its-otu-repseqs.qza \\
--o-classification its-taxonomy.qza
# Tabulate taxonomy
qiime metadata tabulate \\
--m-input-file its-taxonomy.qza \\
--o-visualization its-taxonomy.qzv
# Create barplot for visualisation
qiime taxa barplot \\
--i-table its-otu-table.qza \\
--i-taxonomy its-taxonomy.qza \\
--m-metadata-file metadata_ITS.tsv \\
--o-visualization taxa-bar-plots.qzv
# Tabulate OTU table with taxonomy
qiime metadata tabulate \\
--m-input-file its-otu-table.qza \\
--m-input-file its-taxonomy.qza \\
--m-metadata-file metadata_ITS \\
--o-visualization its-otu-table-with-tax.qzv
## Create merged taxonomy + OTU table
# Export OTU table
qiime tools export \\
--input-path its-otu-table.qza \\
--output-path its-otu-table
# Export taxonomy
qiime tools export \\
--input-path its-taxonomy.qza \\
--output-path its-taxonomy
# Convert biom to tsv
biom convert \\
-i its-otu-table/feature-table.biom \\
-o its-otu-table.tsv \\
--to-tsv
## Add taxonomy to tsv
# Make nano file
nano merge_otu_taxonomy.py
#!/usr/bin/env python3
import csv
import sys
otu_file = "its-otu-table.tsv"
tax_file = "taxonomy.tsv"
output_file = "otu-table-with-taxonomy.tsv"
# Load taxonomy
taxonomy = {}
with open(tax_file, "r") as t:
reader = csv.DictReader(t, delimiter="\\t")
for row in reader:
feature = row\["Feature ID"\]
taxonomy\[feature\] = row\["Taxon"\]
# Open OTU table
with open(otu_file, "r") as f, open(output_file, "w") as out:
reader = csv.reader(f, delimiter="\\t")
writer = csv.writer(out, delimiter="\\t")
header = next(reader)
# Add taxonomy column
header.append("taxonomy")
writer.writerow(header)
# For each OTU
for row in reader:
otu_id = row\[0\]
tax = taxonomy.get(otu_id, "Unassigned")
row.append(tax)
writer.writerow(row)
print("Done! Output written to:", output_file)
# Make executable
chmod +x merge_otu_taxonomy.py
# Run it
./merge_otu_taxonomy.py
# Prepare workspace and set directory for FUNGuild
git clone https://github.com/UMNFuN/FUNGuild
cd /Users/lowelabshared/Desktop/Madi/Madi_Data_AGRF-selected/AGRF_DVPROCAGRF25060388-2_AAHFYLYM5-ITS-Fungi/FUNGuild
# Run the script with default parameters
python Guilds_v1.1.py -otu /Users/lowelabshared/Desktop/Madi/Madi_Data_AGRF-selected/AGRF_DVPROCAGRF25060388-2_AAHFYLYM5-ITS-Fungi/FUNGuild/otu-table-with-taxonomy.tsv -db fungi
```
Any and all help appreciated! Thank you 🙂
I’m brand new to all of this so I apologise if I didn’t make sense or if these are really silly questions.
Cheers 🙂
---
### Author:  [@kranderson](https://forum.qiime2.org/u/kranderson)
#### Post date: [September 28, 2026, 5:17am UTC](https://forum.qiime2.org/t/reformat-otu-table-for-use-in-funguild/33861/2 "2026-09-28T05:17:05Z")
Hi Madi,
Your post is from 2025, so this probably won't be of help to you anymore, but I was looking for FUNGuild tips myself and found your post. I imagine others have done the same, so I wanted to share what I did for any future folks finding themselves here.
The [FUNGuild repository](https://github.com/UMNFuN/FUNGuild) that can be cloned using [git](https://gitforwindows.org/) includes a directory named "example", which contains `otu_table.txt`. This shows formatting in which the feature table has feature ID (_OTU ID_), sample frequency, and taxonomy:
| OTU ID | sample1 | sample2 | sample3 | sample4 | sample5 | taxonomy |
| --- | --- | --- | --- | --- | --- | --- |
| OTU\_100 | 0 | 1 | 0 | 0 | 0 | 93.6%; Laetisaria\_fuciformis; EU118639 SH012042.06FU; reps\_singleton; k\_\_Fungi;p\_\_Basidiomycota;c\_\_Agaricomycetes;o\_\_Corticiales;f\_\_Corticiaceae;g\_\_Laetisaria;s\_\_Laetisaria\_fuciformis |
| OTU\_1002 | 95 | 127 | 183 | 10 | 121 | 100%; Leptodontidium\_sp; FJ552955; SH209316.06FU; refs; k\_\_Fungi;p\_\_Ascomycota;c\_\_Leotiomycetes;o\_\_Helotiales;f\_\_Incertae\_sedis;g\_\_Leptodontidium;s\_\_Leptodontidium\_sp |
| OTU\_1003 | 1 | 0 | 1 | 0 | 0 | 79.31%; uncultured\_fungus; KC966088 SH441311.06FU; reps\_singleton; k\_\_Fungi;p\_\_unidentified;c\_\_unidentified;o\_\_unidentified;f\_\_unidentified;g\_\_unidentified;s\_\_uncultured\_fungus |
🍄🟫🍄🟫🍄🟫
After classifying your samples, your taxonomy table will include the necessary information including _Feature ID_ ([OTU or ASV](https://forum.qiime2.org/t/asv-vs-otu-for-fungal-its/30735)) and _Taxonomy_.
```auto
## Assign taxonomy to sequences using classifier
qiime feature-classifier classify-sklearn \
--i-classifier classifier.qza \
--i-reads sequences.qza \
--o-classification taxonomy.qza
## Visualize feature IDs and taxonomy w/ sequences linked to BLAST
qiime feature-table tabulate-seqs \
--i-data sequences.qza \
--i-taxonomy taxonomy.qza \
--m-metadata-file feat_frequences.qza \
--o-visualization taxonomy.qzv
```
| Feature ID | Taxon: 0 | Frequency | No. of Samples Observed In | Sequence Length | Sequence |
| --- | --- | --- | --- | --- | --- |
| c5f5295b4d6f291b8e3e18974effdba4 | k\_\_Fungi | 4.0 | 1 | 108 | CTTGATCTTCTTGGTGGCTCTATAGCTGCCGTGAACACTGTGAACTGTCTTGTACTGTTGTATTTTTTTGAAAAAAGTTGTATTTTCTTTTGAAAATAGAATATAAGA |
| 38dcb45cc2597fb462fac1e62682daf0 | k\_\_Fungi;p\_\_Basidiomycota;c\_\_Agaricomycetes;o\_\_Agaricales;f\_\_Hymenogastraceae;g\_\_Hymenogaster;s\_\_Hymenogaster\_parksii | 6.0 | 2 | 229 | TTGAATGAACTTGGTGTGGTTGTTGCTGGCCCTATTGGGGCATGTGCACACCTGCCATCCTCATCTCTCCACCTGTGCACCTCTTGTAGACCTGGATAGACTTTCCGAGGCAACTCGGTTGGGAGGAATGCTGCATCAGCTTTCTTTGCGCTTCCAGGCCTATGTTTTTCATAAACCCGTAGTATGTAACAGAATGTATCATTGGGCTTCAGTGCCTATAAACCTTATA |
| d54289cc63c1468cb4ed5ee414f209bd | k\_\_Fungi;p\_\_Ascomycota;c\_\_Sordariomycetes;o\_\_Hypocreales;f\_\_Clavicipitaceae;g\_\_Metapochonia;s\_\_Metapochonia\_sp | 3.0 | 1 | 179 | CCGAGTTTTCTACTCCCAAACCCCTGTGAACTTATACCTTTACCGTTGCTTCGGCGGGTTAACGCCCCGGAAAGGCCCCCGAAAGGGAGCCGCCCCGGAACCAGGCGCCCGCCGGGGGACCCAAACTCTTGTATTTTCTTACCTAGCATGTCTGAGTGGAATCATAAACAAATGAATCA |
🍄🟫🍄🟫🍄🟫
This is when you can collapse the taxonomy to genus level before exporting. When you do, you will lose your feature IDs and have a table with just the frequency of each identified genus (taxonomy) per sample. This is fine, as you only need taxonomy for FUNGuild to work.
```auto
## Collapse by taxonomy
qiime taxa collapse \
--i-table feature_table.qza \
--i-taxonomy taxonomy.qza \
--p-level 6 \
--o-collapsed-table genus_table.qza
## Export genus table to .tsv
qiime tools export \
--input-path genus.qza \
--output-path genus-table
biom convert \
-i genus-table/feature-table.biom \
-o genus_table.tsv \
--to-tsv
```
| # Constructed from biom file | | | |
| --- | --- | --- | --- |
| #OTU ID | 10B1 | 10C1 | 10D1 |
| k\_\_Fungi;p\_\_Basidiomycota;c\_\_Tremellomycetes;o\_\_Tremellales;f\_\_Rhynchogastremaceae;g\_\_Papiliotrema | 332.0 | 0.0 | 173.0 |
| k\_\_Fungi;p\_\_Basidiomycota;c\_\_Tremellomycetes;o\_\_Tremellales;f\_\_Cryptococcaceae;g\_\_Cryptococcus | 4018.0 | 41.0 | 17.0 |
| k\_\_Fungi;p\_\_Basidiomycota;c\_\_Tremellomycetes;o\_\_Filobasidiales;f\_\_Filobasidiaceae;g\_\_Naganishia | 4435.0 | 166.0 | 19.0 |
🍄🟫🍄🟫🍄🟫
As for removing the first row and renaming the first column, you'll have to manually handle that by editing it in a code editor (nano works). I will use Python. The table has taxonomy instead of feature IDs, so I am renaming the first column to "Taxonomy":
```auto
## Read and update the .tsv genus table in Python
import pandas as pd
genus = pd.read_csv('genus_table.tsv', sep='\t', skiprows=1) #ignore the first row
genus.columns.values[0] = 'Taxonomy' #rename first column
genus.to_csv("genus_table.tsv", sep='\t') #overwrite previous table
```
| Taxonomy | 10B1 | 10C1 | 10D1 |
| --- | --- | --- | --- |
| k\_\_Fungi;p\_\_Basidiomycota;c\_\_Tremellomycetes;o\_\_Tremellales;f\_\_Rhynchogastremaceae;g\_\_Papiliotrema | 332.0 | 0.0 | 173.0 |
| k\_\_Fungi;p\_\_Basidiomycota;c\_\_Tremellomycetes;o\_\_Tremellales;f\_\_Cryptococcaceae;g\_\_Cryptococcus | 4018.0 | 41.0 | 17.0 |
| k\_\_Fungi;p\_\_Basidiomycota;c\_\_Tremellomycetes;o\_\_Filobasidiales;f\_\_Filobasidiaceae;g\_\_Naganishia | 4435.0 | 166.0 | 19.0 |
🍄🟫🍄🟫🍄🟫
The table is ready at this point to be fed into FUNGuild by following the instructions in the [README](https://github.com/UMNFuN/FUNGuild/blob/master/README.md):
```auto
## Clone repo and change working directory to FUNGuild
git clone https://github.com/UMNFuN/FUNGuild
cd FUNGuild/
## Produce separate tables for assigned (-m) and unassigned (-u) functional info
python Guilds_v1.1.py -otu /Users/username/Documents/project/genus_table.tsv -db fungi -m -u
```
| Taxonomy | 10B1 | 10C1 | 10D1 | Taxon | Taxon Level | Trophic Mode | Guild | Growth Morphology | Trait | Confidence Ranking | Notes | Citation/Source |
| --- | --- | --- | --- | --- | --- | --- | --- | --- | --- | --- | --- | --- |
| k\_\_Fungi;p\_\_Basidiomycota;c\_\_Tremellomycetes;o\_\_Tremellales;f\_\_Rhynchogastremaceae;g\_\_Papiliotrema | 332.0 | 0.0 | 173.0 | Papiliotrema | 13 | Pathotroph | Fungal Parasite | Dimorphic | NULL | Probable | As mycoparasite (P�lme et al. 2020); Decay fungal material (P�lme et al. 2020) | b'P\xc3\xb5lme S, et al. 2020. Fungal Diversity 105:1-16 (([Client Challenge](https://doi.org/10.1007/s13225-020-00466-2)))' |
| k\_\_Fungi;p\_\_Basidiomycota;c\_\_Tremellomycetes;o\_\_Tremellales;f\_\_Cryptococcaceae;g\_\_Cryptococcus | 4018.0 | 41.0 | 17.0 | Cryptococcus | 13 | Pathotroph-Saprotroph-Symbiotroph | Animal Pathogen-Endophyte-Epiphyte-(Undefined Saprotroph) | Dimorphic Yeast-Yeast | NULL | Possible | As foliar\_endophyte (P�lme et al. 2020); Decay leaf, fruit, seed, soil, dung, animal material (P�lme et al. 2020) | b'Andrews JH, et al. 1983. Phytopathology 73:228-234 (([https://doi.org/10.1094/Phyto-73-228](https://doi.org/10.1094/Phyto-73-228))); Kurtzman CP, et al. (eds.) 2011. The Yeasts, a Taxonomic Study. Fifth Edition. Vols 1-3. Elsevier, San Diego (ISBN: 9780444521491); P\xc3\xb5lme S, et al. 2020. Fungal Diversity 105:1-16 (([Client Challenge](https://doi.org/10.1007/s13225-020-00466-2)))' |
| k\_\_Fungi;p\_\_Ascomycota;c\_\_Eurotiomycetes;o\_\_Eurotiales;f\_\_Aspergillaceae;g\_\_Penicillium | 0.0 | 0.0 | 3.0 | Penicillium | 13 | Pathotroph-Saprotroph-Symbiotroph | Animal Parasite-Dung Saprotroph-Endophyte-Fungal Parasite-Plant Pathogen-(Undefined Saprotroph)-Wood Saprotroph | Microfungus | Soft Rot | Highly Probable | As foliar\_endophyte (P�lme et al. 2020); As mycoparasite (P�lme et al. 2020); Decay soil (P�lme et al. 2020) | b'Duncan CG, Eslyn WE. 1966. Mycologia 58:642-664 (([Client Challenge](https://doi.org/10.2307/3757045))); Seehann G, et al. 1975. List of Fungi in Soft-Rot Tissue Tests. Institute fur Holzbiologie und Holzschutz, Bundesforschungsanstalt fur Forst - und Holzwirtshaft, Hamburg - Lohbrugge, Germany (([List of fungi in soft-rot tests](https://www.irg-wp.com/irgdocs/details.php?d6493033-c9ea-40f3-8e3e-5697f32d640d))); Costa IPMW, et al. 2012. Mycotaxon 119:e26 (([http://mycotaxon.com/resources/checklists/costa\_v119\_checklist.pdf](http://mycotaxon.com/resources/checklists/costa_v119_checklist.pdf))); Bills GF, et al. 2013. Current Opinion in Microbiology 16:549-565 (([Redirecting](https://doi.org/10.1016/j.mib.2013.08.001))); Tedersoo L, et al. 2014. Science 346:e1256688 (([https://doi.org/10.1126/science.1256688](https://doi.org/10.1126/science.1256688))); P\xc3\xb5lme S, et al. 2020. Fungal Diversity 105:1-16 (([Client Challenge](https://doi.org/10.1007/s13225-020-00466-2)))' |
---
### Author:  [@Nicholas\_Bokulich](https://forum.qiime2.org/u/Nicholas_Bokulich)
#### Post date: [September 28, 2026, 6:24am UTC](https://forum.qiime2.org/t/reformat-otu-table-for-use-in-funguild/33861/3 "2026-09-28T06:24:35Z")
Hi @kranderson and @mhog ,
there is also now a QIIME 2 plugin for fungal trait prediction based on the Fungal Traits database (which is newer/based on FUNguild). You can see the tutorial here, using this tool should save time vs. exporting and reformatting to integrate QIIME 2 results with FUNguild, e.g., to classify according to fungal guilds:
> [@q2-fungal-traits: a QIIME 2 plugin for trait-based analysis of fungal microbiome data](https://forum.qiime2.org/t/q2-fungal-traits-a-qiime-2-plugin-for-trait-based-analysis-of-fungal-microbiome-data/34235):
>
> Hi everyone, We are excited to share a new plugin, [q2-fungal-traits](https://github.com/bokulich-lab/q2-fungal-traits), for automated integration of fungal taxonomy derived from marker-gene amplicon (e.g., ITS, other regions) or shotgun metagenomic sequencing data with ecological and functional trait information compiled from published fungal trait datasets. The plugin provides an annotate action that generates a metadata table containing fungal trait annotations and spore size estimates based on fungal taxonomic assignments. These annotations…
I hope that helps!